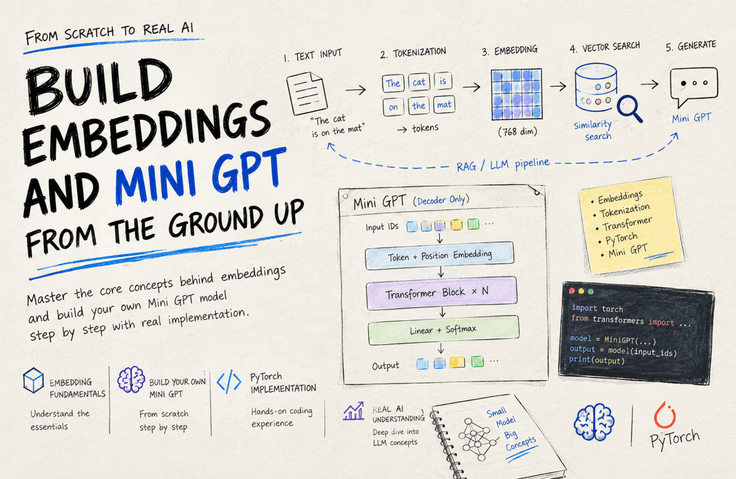
"I used the OpenAI Embeddings API" and "I implemented an 820,000-parameter Transformer from scratch without a framework" are two different statements. To write the latter, you need to open it up and see what’s inside—and that’s what this course is about.
This is how I write it on my résumé.
01
Implemented an 820,000-parameter transformer language model in TypeScript without a deep learning framework
Coded everything from designing the self-attention architecture to training and sentence generation, then trained it on Shakespeare's plays
02
Implemented automatic differentiation and backpropagation from scratch, manually reproducing the computations handled by frameworks
Built the component that calculates which values to adjust and by how much, then used it to train a small neural network and confirmed that the loss decreased
03
Trained Word2Vec skip-gram from scratch and verified semantic clustering using cosine similarity
Without providing any rules, we only told it "try to predict the surrounding words," yet cat·dog scored 0.697 while cat·stock market scored 0.432
04
Built a BPE tokenizer from scratch and completed the pipeline through sentence-level embeddings
This covered everything from rules for splitting long texts into chunks a model can process to turning an entire sentence into numbers
05
Compare your own model with public models using the same criteria and quantify the performance differences
You can explain what differs, by how much, and where those differences come from, with supporting evidence
06
Diagnose the causes of abnormal embedding results by separating them into training volume and dimensionality
As someone who understands the internals rather than merely calling the API, you can determine where to look first
All six lines are things you will build and measure yourself in this course. Even if you’re asked in an interview, "So what happens inside?", you’ll still have something to say.