<LLM: Learning by Building from Scratch> Commentary Lecture
This course covers the GitHub notebooks and bonus content for <Building an LLM from Scratch> (Gilbut, 2025). GitHub: https://github.com/rickiepark/llm-from-scratch/
<Building an LLM from Scratch> is the Korean translation of the bestseller <Build a Large Langauge Model (from Scratch)> (Manning, 2024) written by Sebastian Raschka. Starting from scratch and building a complete version of OpenAI’s GPT-2 model, this book provides a way to learn how large language models work and how to use them.
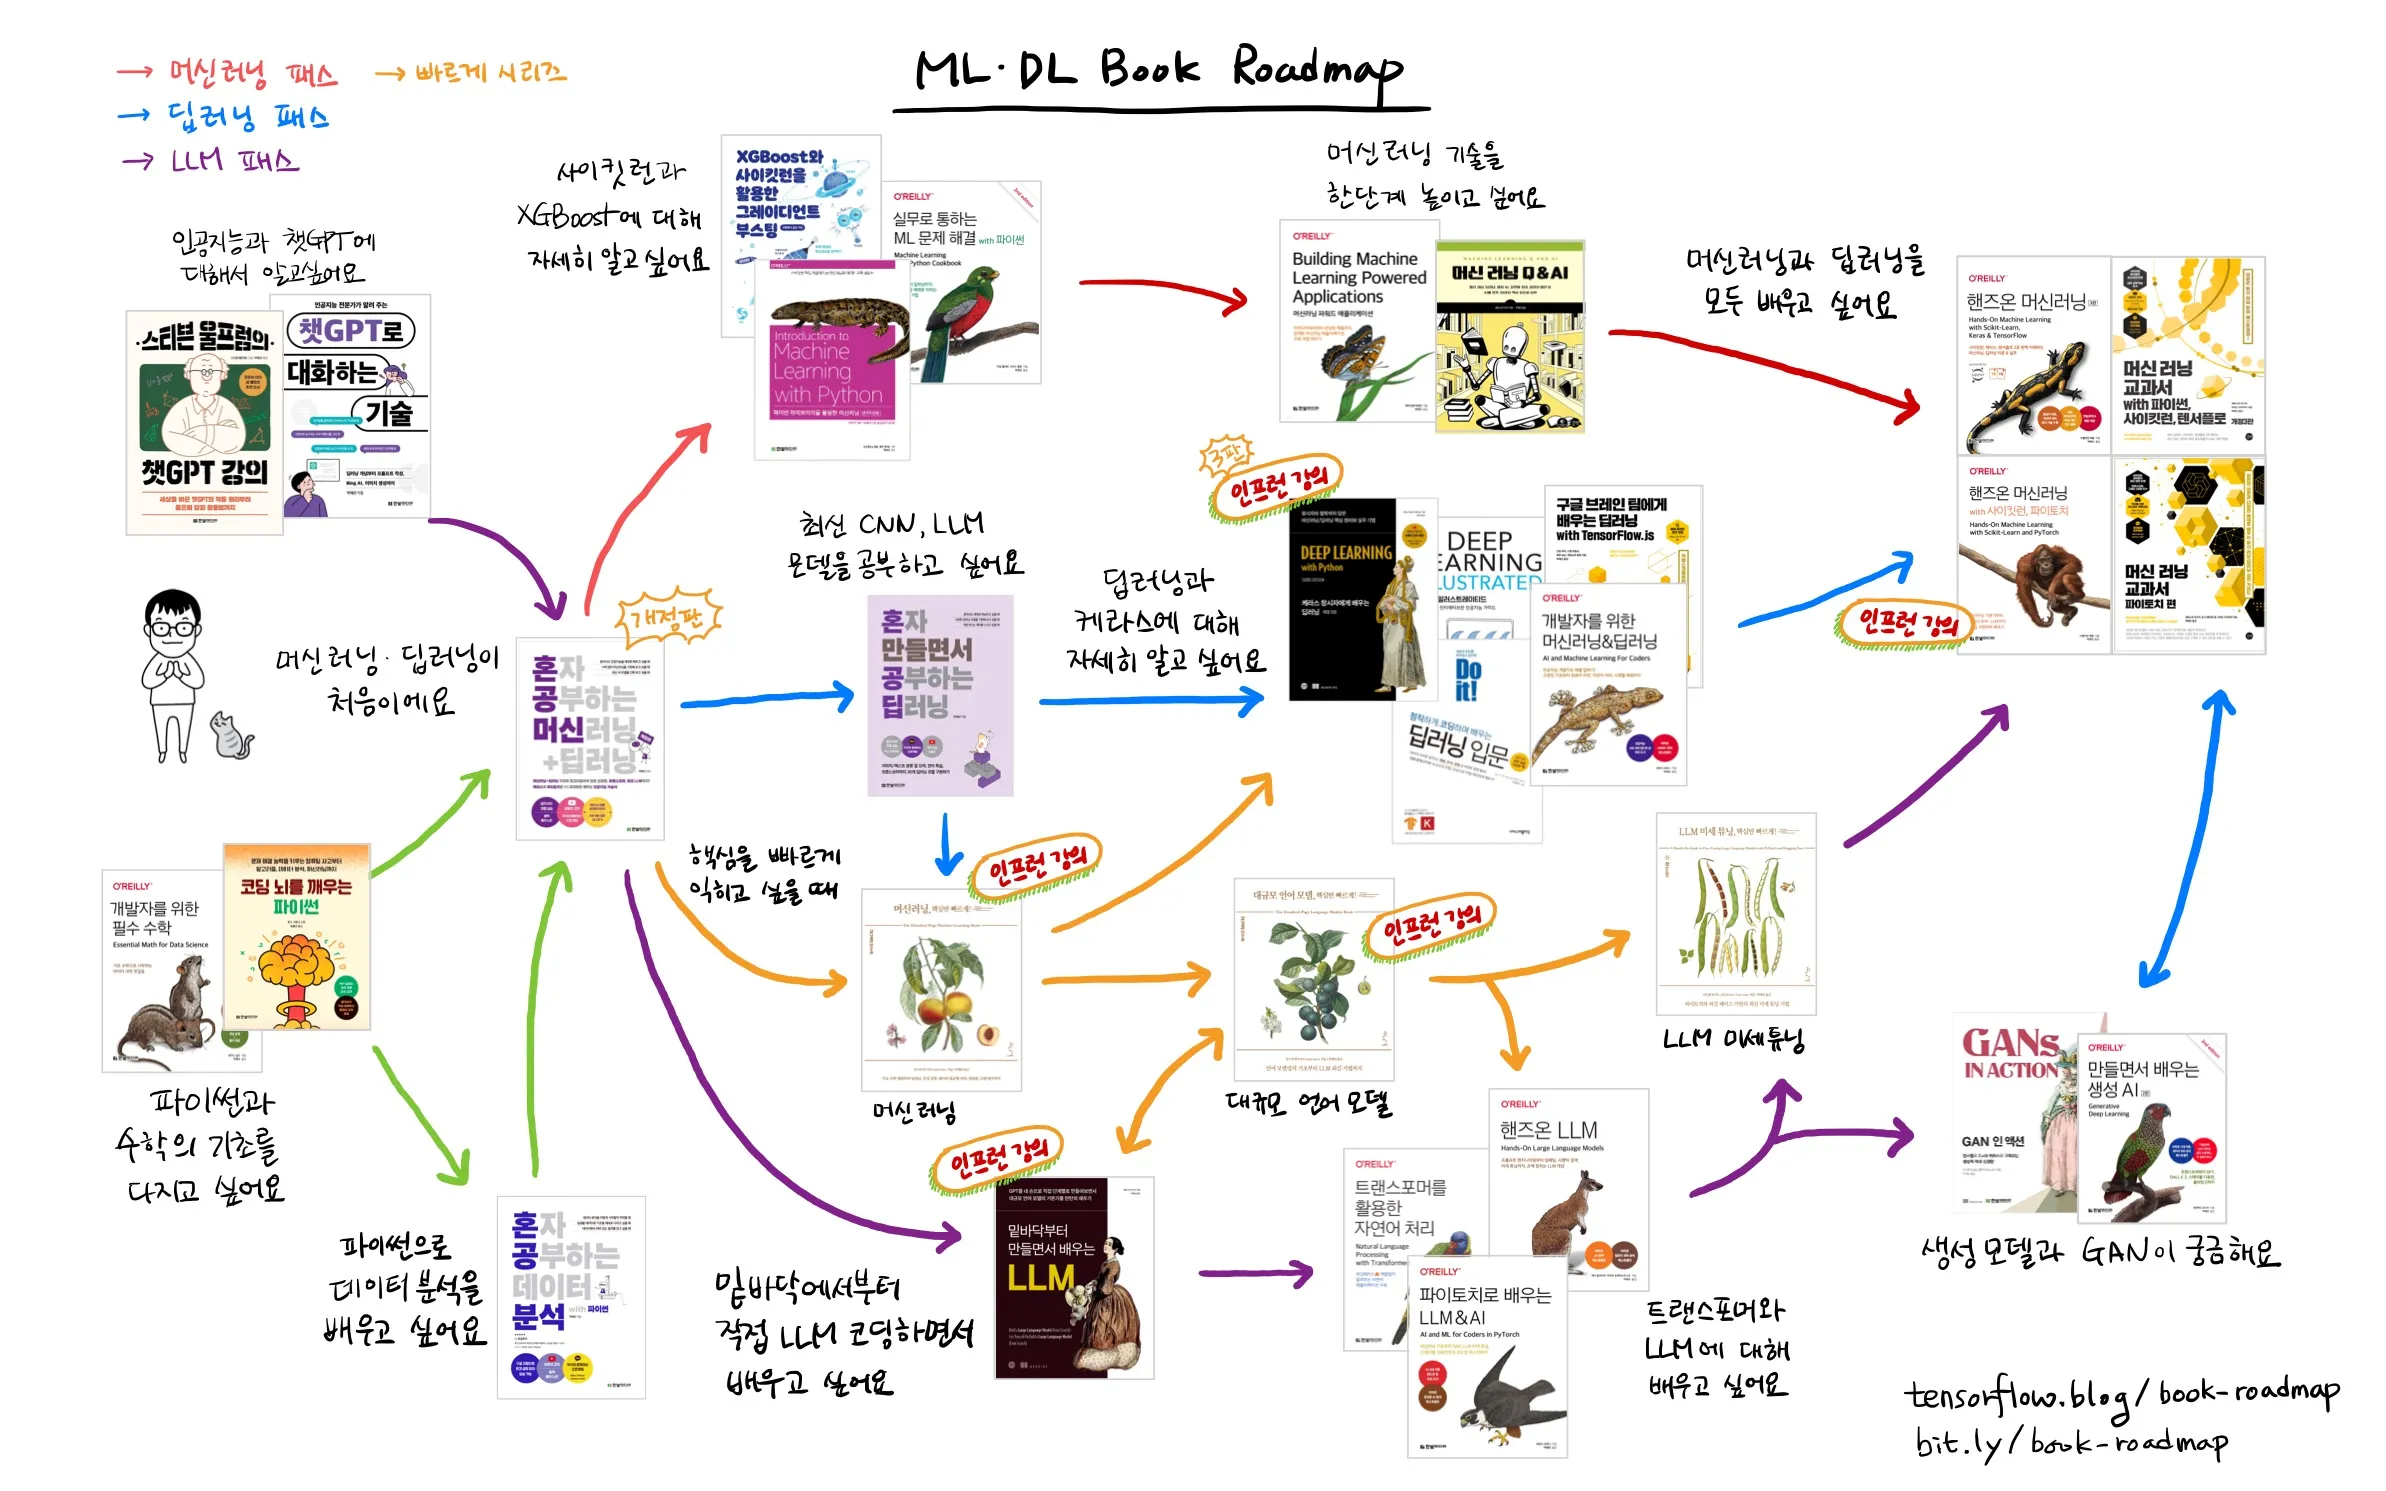
I studied in the following order:
Challenge lecture attendance - Book reading - Source analysis lecture attendance
I will continue with Large Language Models Core Concepts Quickly.
5.0
김진철
14% enrolled
Working hard.....😊
5.0
든든한꼬마
65% enrolled
Thank you for the great lecture.
What you will gain after the course
Starting from scratch, implement a complete LLM entirely in code.
Learn the core components that make up LLMs, including transformers and attention.
Learn how to pretrain an LLM similar to GPT.
Learn how to fine-tune an LLM for classification.
Learn how to fine-tune an LLM to respond according to human instructions.
Discount News
<Hands-On Machine Learning with Scikit-Learn and PyTorch> Complete Reading Challenge (https://inf.run/5SDwX): Register to receive a 50% discount coupon for this course!
This course explains the example code provided with <LLM from Scratch>. The GitHub repository (https://github.com/rickiepark/llm-from-scratch/) includes not only the example code from the book but also a variety of supplementary materials. Explanations of this supplementary content are also provided.
Anyone can take this course without purchasing the book. However, it is most effective when taken alongside the book. Some code explanations may be difficult to understand without referring to the book. The prerequisite knowledge required is Python programming. Experience with deep learning and PyTorch will be helpful. If you are new to both of these concepts, read Appendix A first.
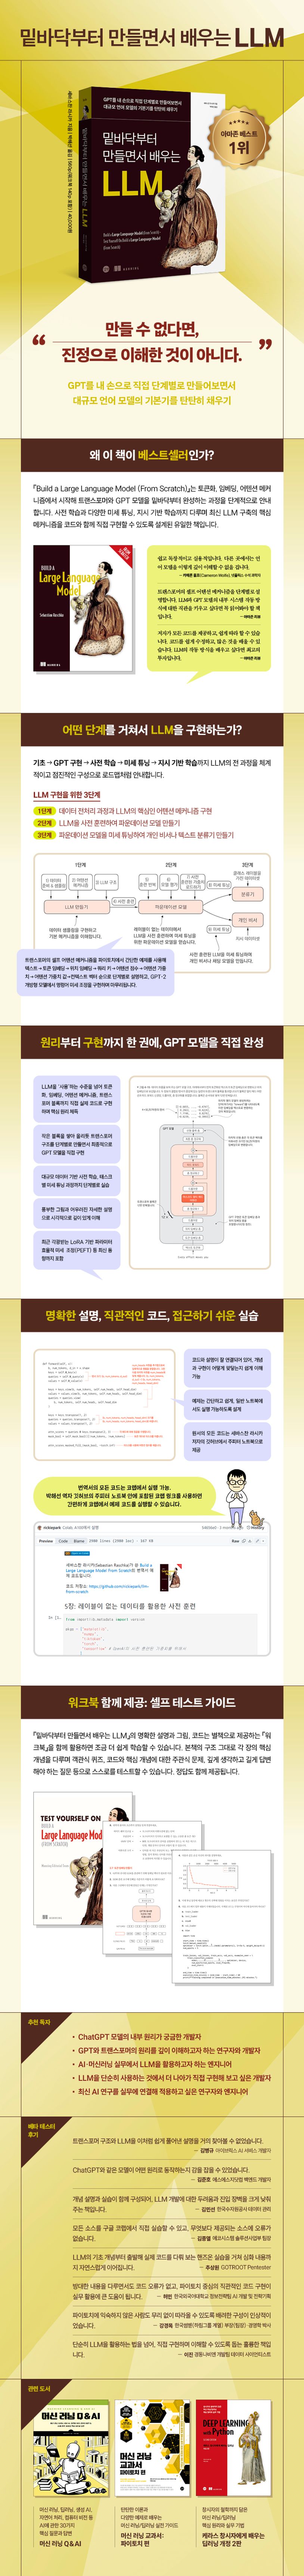
Follow the code line by line, and you'll build your very own GPT! A practical guide to implementing GPT from scratch and gaining a hands-on understanding of how LLMs work
Difficult concepts are explained through illustrations, and you learn by building an LLM yourself. This practical introduction to LLMs lets you learn by implementing the structure and operating principles of large language models firsthand, from start to finish. Rather than simply explaining concepts, it begins with text preprocessing, tokenization, and embeddings, then guides you step by step through building self-attention, multi-head attention, and Transformer blocks. You will then integrate these components to complete an actual GPT model and work directly with the key elements of modern architecture design, including the number of model parameters, techniques for stabilizing training, activation functions, and normalization methods. The book also provides in-depth guidance on pretraining and fine-tuning. You can practice pretraining on unlabeled data, tuning the model for downstream tasks such as text classification, and applying instruction-based learning techniques that have recently gained attention. It also covers the latest topics, such as parameter-efficient fine-tuning (PEFT) based on LoRA, offering broad insight into how to connect LLMs to real-world services and research. Every concept is implemented in PyTorch code and optimized for hands-on practice in a standard laptop environment. By following the implementation process in this book, you will naturally come to understand what happens inside an LLM and gain an intuitive, hands-on understanding of how the mechanisms of large language models work.
Recommended for these people
Who is this course right for?
Those who want to gain a detailed understanding of how large language models (LLMs) work
Those who want to pretrain and fine-tune LLMs using PyTorch and the transformers package
People who want to know the architecture of OpenAI’s GPT-2 model
For those who can’t rest until they’ve tried making everything themselves!
Need to know before starting?
Basic knowledge of Python programming is required.
Although I majored in mechanical engineering, I have worked continuously reading and writing code since graduating. I am a Google AI/Cloud GDE. I run the TensorFlow blog (tensorflow.blog) and explore the fascinating boundary between software and science by writing and translating books about machine learning and deep learning.
I have written 『Deep Learning You Study by Building It Yourself』 (Hanbit Media, 2025), 『Self-Study Machine Learning + Deep Learning (Revised Edition)』 (Hanbit Media, 2025), 『Self-Study Data Analysis with Python』 (Hanbit Media, 2023), 『The Art of Conversing with ChatGPT』 (Hanbit Media, 2023), and 『Do it! Introduction to Deep Learning』 (Aegis Publishing, 2019).
『Hands-On Machine Learning with Scikit-Learn and PyTorch』(Hanbit Media, 2026), 『Deep Learning from the Keras Creator (3rd Edition)』(Gilbut, 2026),『LLM Fine-Tuning, Fast and Focused!』(Insight, 2026), 『LLM & AI with PyTorch』(Hanbit Media, 2026), 『Large Language Models, Fast and Focused!』(Insight, 2025), 『Machine Learning, Fast and Focused!』(Insight, 2025), 『Learn LLMs by Building from Scratch』(Gilbut, 2025), 『Hands-On LLM』(Hanbit Media, 2025), 『Machine Learning Q & AI』(Gilbut, 2025), 『Mathematics for Developers』(Hanbit Media, 2024), 『Practical ML Problem Solving with Python』(Hanbit Media, 2024), 『Machine Learning Textbook: PyTorch Edition』(Gilbut, 2023), 『Stephen Wolfram's ChatGPT Course』(Hanbit Media, 2023), 『Hands-On Machine Learning, 3rd Edition』(Hanbit Media, 2023), 『Generative Deep Learning by Building, 2nd Edition』(Hanbit Media, 2023), 『Python That Awakens Your Coding Brain』(Hanbit Media, 2023), 『Natural Language Processing with Transformers』(Hanbit Media, 2022), 『Deep Learning from the Keras Creator, 2nd Edition』(Gilbut, 2022), 『Machine Learning&Deep Learning for Developers』(Hanbit Media, 2022), 『Gradient Boosting with XGBoost and Scikit-Learn』(Hanbit Media, 2022), 『Learn Deep Learning with the Google Brain Team with TensorFlow.js』(Gilbut, 2022), and 『Machine Learning with Python Machine Learning Libraries (2nd Revised Edition)』(Hanbit Media, 2022), among several dozen books translated into Korean.
I studied in the following order:
Challenge lecture attendance - Book reading - Source analysis lecture attendance
I will continue with Large Language Models Core Concepts Quickly.