


모의고사 1유형
모의고사 1회 입니다
아래 코드에 틀린건 없을까요?
최종적으로 제출할때 print는 여기에 1개만 있어야하는거죠?
print(roc_auc_score(y_val, pred[:,1])) 평가지표에 print 하면 안되는거맞죵? 확인부탁드립니다.
#기출1회
import pandas as pd
train = pd.read_csv("data/customer_train.csv")
test = pd.read_csv("data/customer_test.csv")
#***********************데이터확인
# print(train.shape, test.shape)
# print(train.head()) #target=성별
# print(test.head())
#문자형2개
# print(train.info())
#결측치 있음
# print(train.isnull().sum())
# 환불금액 2295
# print(test.isnull().sum())
# 환불금액 1611
#***********************전처리 *결합it인
#결측치제거/있음
train['환불금액']=train['환불금액'].fillna(0)
test['환불금액']=test['환불금액'].fillna(0)
#train합치기/없음
# pd.concat([X_train, y_train['성별']],axis=1)
#id없애기/있음
train= train.drop('회원ID',axis=1)
test_id= test.pop('회원ID')
#t타켓
target=train.pop('성별')
#인코딩
from sklearn.preprocessing import LabelEncoder
# from sklearn import preprocessing
# print(dir(preprocessing))
# print(help(preprocessing.LabelEncoder))
cols= train.select_dtypes(include='object').columns
for col in cols :
le= LabelEncoder()
train[col] = le.fit_transform(train[col])
test[col] = le.transform(test[col])
#***********************분리
from sklearn.model_selection import train_test_split
from sklearn import model_selection
# print(dir(model_selection))
# print(help(model_selection.train_test_split))
X_tr, X_val, y_tr, y_val = train_test_split(
train,
target,
test_size=0.2,
random_state=2022
)
#***********************모델
from sklearn.ensemble import RandomForestClassifier
# model= RandomForestClassifier(random_state=0)
model= RandomForestClassifier(random_state=0, max_depth=7, n_estimators=1000)
model.fit(X_tr, y_tr)
pred= model.predict_proba(X_val)
#***********************평가
from sklearn.metrics import roc_auc_score
# from sklearn import metrics
# print(dir(metrics))
# print(help(metrics.roc_auc_score))
print(roc_auc_score(y_val, pred[:,1]))
# 0.6186558526810393 (random_state=0)
# 0.6641618297401879 (random_state=0, max_depth=7, n_estimators=1000)
#***********************예측
pred= model.predict_proba(test)[:,1]
result= pd.DataFrame({
'pred':pred
})
#***********************저장
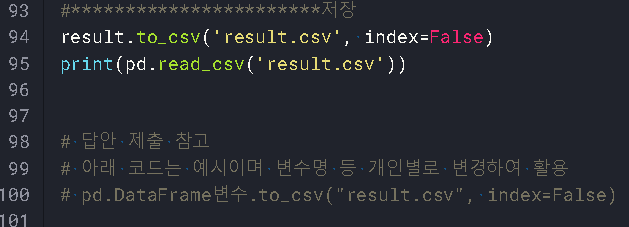
result.to_csv('result.csv', index=False)
print(pd.read_csv('result.csv'))
답변 1
수강기간 연장 관련 문의
0
14
2
작업형2모의문제3_updated2026.10
0
29
2
안녕하세요. 수강연장 신청드립니다
0
19
2
코랩 링크
0
16
2
작업형2 모의문제2 updated 2026.10 질문
0
30
2
카이제곱 독립성검정 질문합니다.
0
29
2
기출 7회 작업형2 평가지표 문의드립니다.
0
23
2
수강연장 문의 드립니다!
0
32
3
수강연장 문의드립니다
0
30
3
작업형2모의문제3_updated2026.10
0
36
2
작업형2 모의문제3_updated2026.10
0
35
2
38강에서 불균형 데이터 처리하는 stratify를 꼭 해줘야하는건지 질문합니다.
0
30
2
수강강의 연장 관련 문의
0
43
2
작업형1_연습문제1 section2
0
44
2
수강기간 연장 문의드립니다
0
48
2
작업형2 모의문제2_updated2026.10
0
54
2
수강기간 연장문의
0
45
2
작업형 2 질문
0
50
2
강의 연장 관련하여 문의드립니다.
0
53
2
섹션7 자료 다운로드
0
52
2
작업형 1 연습문제 Section12
0
54
2
수강기간 연장 문의
0
64
2
안녕하세요, 혹시 수강기간 연장이 가능할까요?
0
55
2
판다스 강의자료는 어디서 받을 수 있나요?
0
66
2