


"모의고사2" 질문
선생님!!
궁금한 점을 질문드리면 항상 빠른 답변 드리시는 점에 감사드립니다.
"모의고사2" 관련하여 궁금한점을 질문드립니다.
평가지표가 f1 인데, f1도 점수가 높은 경우 성능이 좋은건가요? 만약 하이퍼파라미터 투닝을 할 경우 f1 점수가 높게 나오는 것으로 test 데이터를 에측해서 csv 화일을 작성해야 하는 건지요?
'모의고사2'를 시험환경에서 연습하는데, 랜덤포레스트는 큰 문제 없이 진행되었는데, xgboost 모델로 할 경우 진행이 안되고 에러가 발생합니다.
이유가 무엇이고 어떻게 수정해야 하는지요?
답변 2
1
네~ f1스코어 높은 것이 좋습니다.
분류 평가 지표의 경우 대부분 높은 것이 좋고
회귀 평가 지표는 e가 붙어 있으면 에러 값이에요 대부분 작을 수록 좋습니다 (R2제외)전체코드를 올려주시겠어요?
0
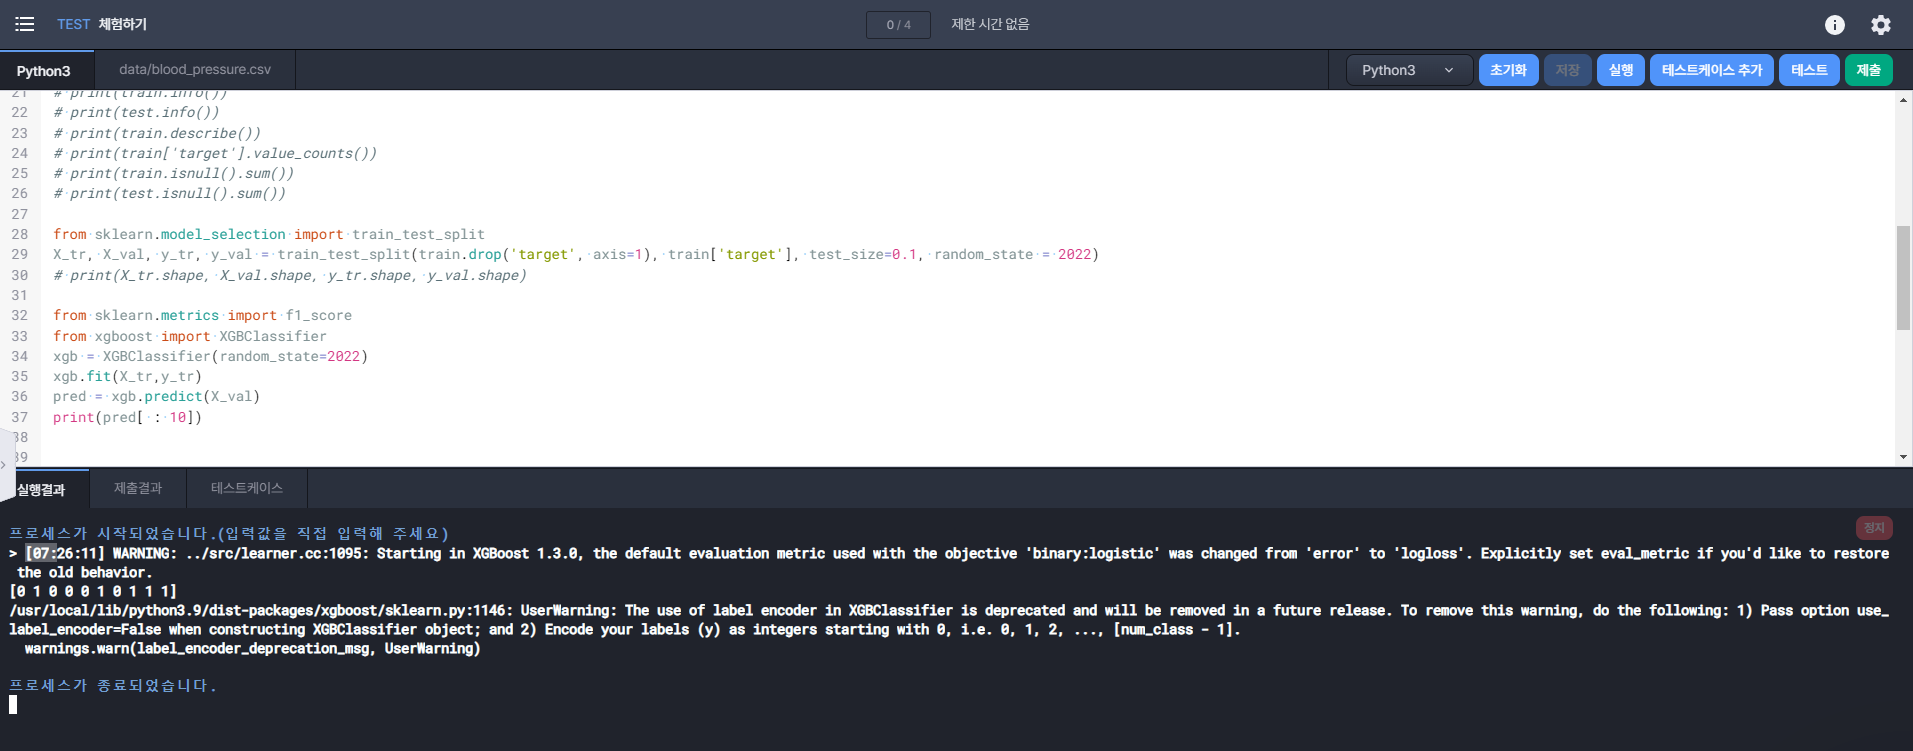
아래 제가 작성한 코드입니다.
import pandas as pd
train = pd.read_csv("train.csv")
test = pd.read_csv("test.csv")
pd.set_option('display.max_columns', None)
# print(train.shape, test.shape)
# print(train.head(3))
# print(train.info())
# print(train.describe())
# print(train.isnull().sum())
from sklearn.model_selection import train_test_split
X_tr, X_val, y_tr, y_val = train_test_split(train.drop('target',axis=1), train['target'], test_size=0.1, random_state=2022)
# print(X_tr.shape, X_val.shape, y_tr.shape, y_val.shape)
# from sklearn.metrics import f1_score
# from sklearn.ensemble import RandomForestClassifier
# model = RandomForestClassifier(random_state=2022)
# model.fit(X_tr, y_tr)
# pred = model.predict(X_val)
# print(pred[:10])
# print(f1_score(y_val, pred))
from sklearn.metrics import f1_score
from xgboost import XGBClassifier
xgb = XGBClassifier(random_state=2022)
xgb.fit(X_tr, y_tr)
pred = xgb.predict(X_val)
print(pred[:10])
아래는 에러 내용입니다.
프로세스가 시작되었습니다.(입력값을 직접 입력해 주세요)
> [23:06:53] WARNING: ../src/learner.cc:1095: Starting in XGBoost 1.3.0, the default evaluation metric used with the objective 'binary:logistic' was changed from 'error' to 'logloss'. Explicitly set eval_metric if you'd like to restore the old behavior.
[0 1 0 0 0 1 0 1 1 1]
/usr/local/lib/python3.9/dist-packages/xgboost/compat.py:31: FutureWarning: pandas.Int64Index is deprecated and will be removed from pandas in a future version. Use pandas.Index with the appropriate dtype instead.
from pandas import MultiIndex, Int64Index
/usr/local/lib/python3.9/dist-packages/xgboost/sklearn.py:1146: UserWarning: The use of label encoder in XGBClassifier is deprecated and will be removed in a future release. To remove this warning, do the following: 1) Pass option use_label_encoder=False when constructing XGBClassifier object; and 2) Encode your labels (y) as integers starting with 0, i.e. 0, 1, 2, ..., [num_class - 1].
warnings.warn(label_encoder_deprecation_msg, UserWarning)
/usr/local/lib/python3.9/dist-packages/xgboost/data.py:208: FutureWarning: pandas.Int64Index is deprecated and will be removed from pandas in a future version. Use pandas.Index with the appropriate dtype instead.
from pandas import MultiIndex, Int64Index
프로세스가 종료되었습니다.
1
안녕하세요 xgb 파라미터값을 수정하는 것 외에도 판다스 인덱스를 수정해야 할 것 같아요.
저는 lightgbm을 주로 사용하는데 xgb말고 이걸 추천할게요!!
(영상을 만들땐 lightgbm을 지원을 안 했어서 못넣었거든요)
lightGBM은
XGBoost와 함께 인기있는 부스팅계열 모델입니다.
학습과 예측 속도가 XGBoost에 비해 빠릅니다.
####### 분류 #######
import lightgbm as lgb
model = lgb.LGBMClassifier()
model.fit(X_train, y_train)
y_pred = model.predict(X_test)
####### 회귀 #######
import lightgbm as lgb
model = lgb.LGBMRegressor()
model.fit(X_train, y_train)
y_pred = model.predict(X_test)
# 하이퍼파라미터 튜닝은 모의고사3 - xgboost 영상과 동일하게 사용하면 됩니다.
작업형2에서 데이터 분포를 확인하는 이유
0
17
2
10회 기출 작업형 2 문제
0
18
1
코딩팡 프로 인증
0
22
1
이번 강의 학습노트
0
18
2
캐글 질문
0
17
2
코딩팡 pro 관련
0
20
1
9번질문입니다.
0
22
2
시험에 대해서
0
21
2
12회 작업형 2
0
25
2
copy()
0
26
2
딴짓코치 이용
0
21
1
수강 관련 문의 드립니다.
0
62
4
자치구 상점 수 합(12회)
0
29
1
불균형데이터 처리 전후 비교
0
34
2
레이블인코딩/원핫
0
44
2
인코딩
0
43
2
작업형 2 작업
0
42
2
ttest_rel() 관련 질문
0
51
2
작업형2. 인코딩에 대해 질문드립니다.
0
39
2
작업형3 2-3
0
47
1
코딩팡 2호선 전처리 종합 28번 중고 카메라 매입가 문제 최적화 질문드립니다.
0
40
1
8회 작업형2
0
39
2
작업형2 모의문제2 updated 2026.10
0
54
3
단순선형 회귀분석 신뢰구간,예측구간 관련질문
0
48
2