Building the Basics of R Programming
coco
This course covers the basics of R programming for those who have no knowledge of R programming.
Beginner
R
You will learn how to collect and manage all stocks listed on the stock market. Through automation, you will collect stock prices daily and even create a dashboard using Shiny to identify stock trends by industry.


Reviews from Early Learners
5.0
DT로
It's great for practical assignments.
5.0
hakjuknu
Good!
5.0
조정태
I am very satisfied with the lecture content. I will continue to review it so that I can fully understand it. Thank you.
Collect all KOSPI/KOSDAQ stocks
Stock Data Management by Industry
Identifying stock trends by industry
🙆🏻♀ Automate everything from collecting and managing all stock data to managing stocks by sector 🙆🏻♂
Do you want to analyze specific stocks of interest or all stocks listed on the KOSPI/KOSDAQ?
To perform an analysis, you need data.
This course is about collecting and managing all stocks listed on the Korean stock market.
Due to time constraints, the course covers collecting the last 3 years of data for all stocks, but
you can easily collect 10 years of data by simply changing 3 to 10.
Starting today, we will collect not only the data from the past 10 years but also newly generated data, specifically the data generated the following day.
Through automation, we will update the stocks daily by collecting the day's trading data around 4:00 PM when the stock market closes.
We will create a Shiny Dashboard like the one at the address below.
https://leegt.shinyapps.io/shiny/
(Access may be restricted if more than a certain number of people connect at once)
All companies (stocks) listed on the stock market have their own unique codes.
The crawling address changes depending on these codes.
Therefore, we first collect the unique codes for each company.
Additionally, we perform preprocessing on the codes so that they can be retrieved from Naver Finance.
After setting the Naver Finance address for each stock, we collect the last three years of data for all stocks.
Since it took about 4 hours for three years of data, I expect it will take around 12 hours to complete the collection for 10 years of data.
After collecting the daily stock data for each item, create a folder for each item and save it within its respective folder.
In addition, implement exception handling to prepare for any potential errors.
We cannot scrape 10 years' worth of data every single day like this. It is highly inefficient.
Instead, once today's stock trading ends, we automate the process by collecting only today's stock data and merging it with the previously stored data.
Now, we can automatically update all daily stock data every day at 4 PM.
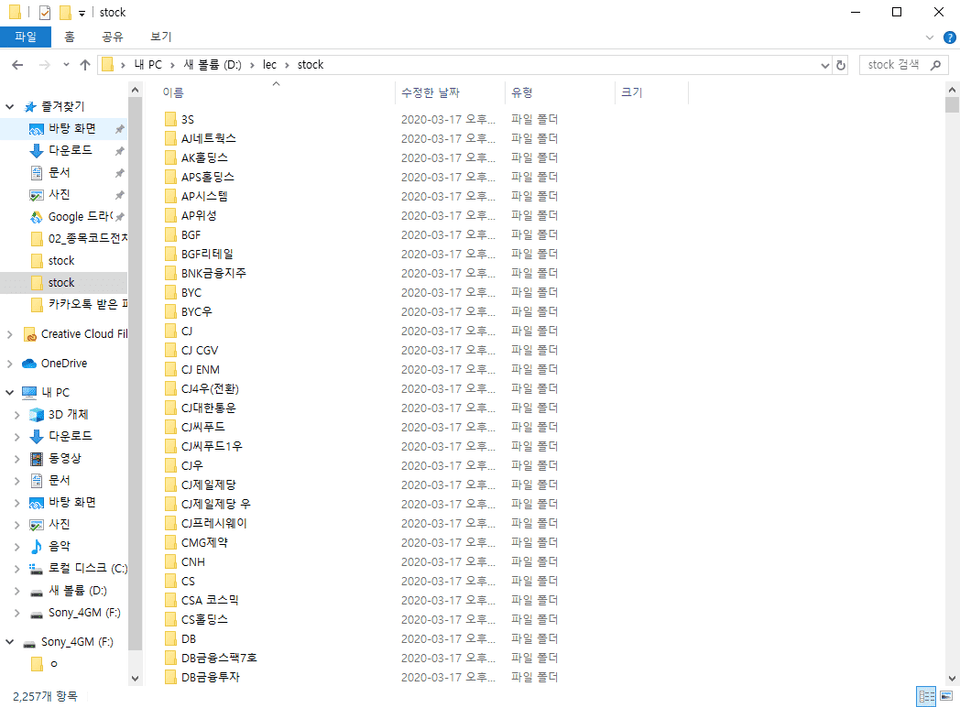
From a medium- to long-term stock investment perspective, it is important to identify trends by industry/theme.
We will collect stock codes by industry, load data for these stocks, identify trends, and visualize them.
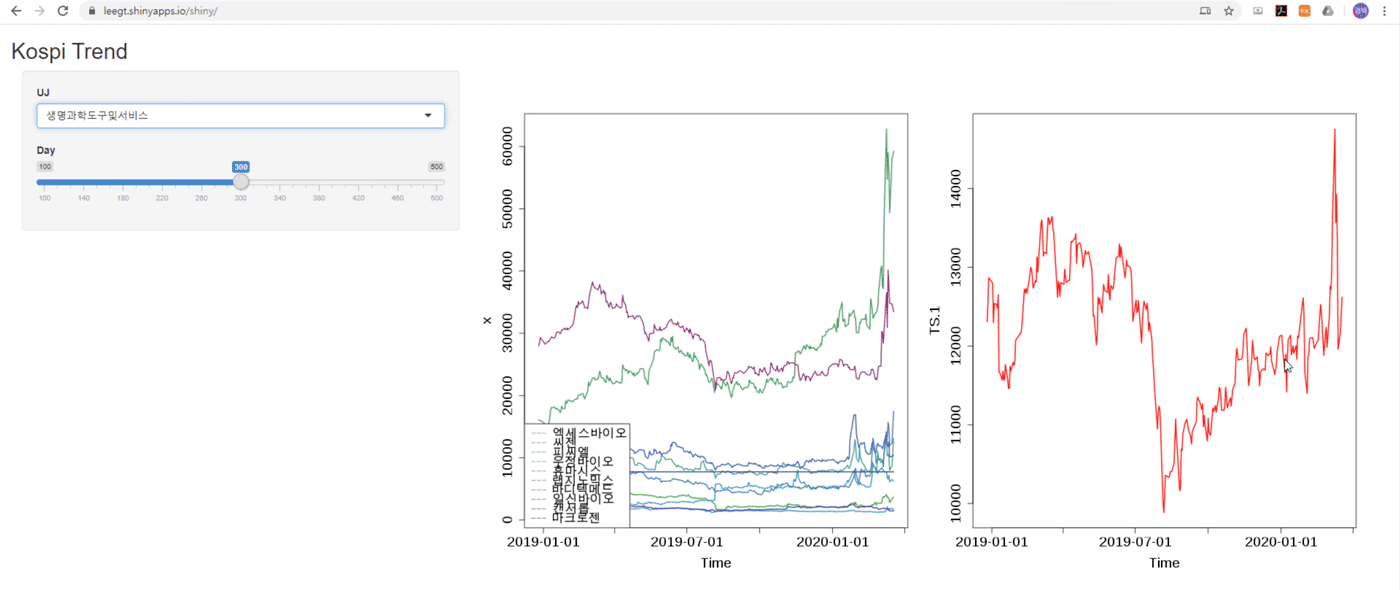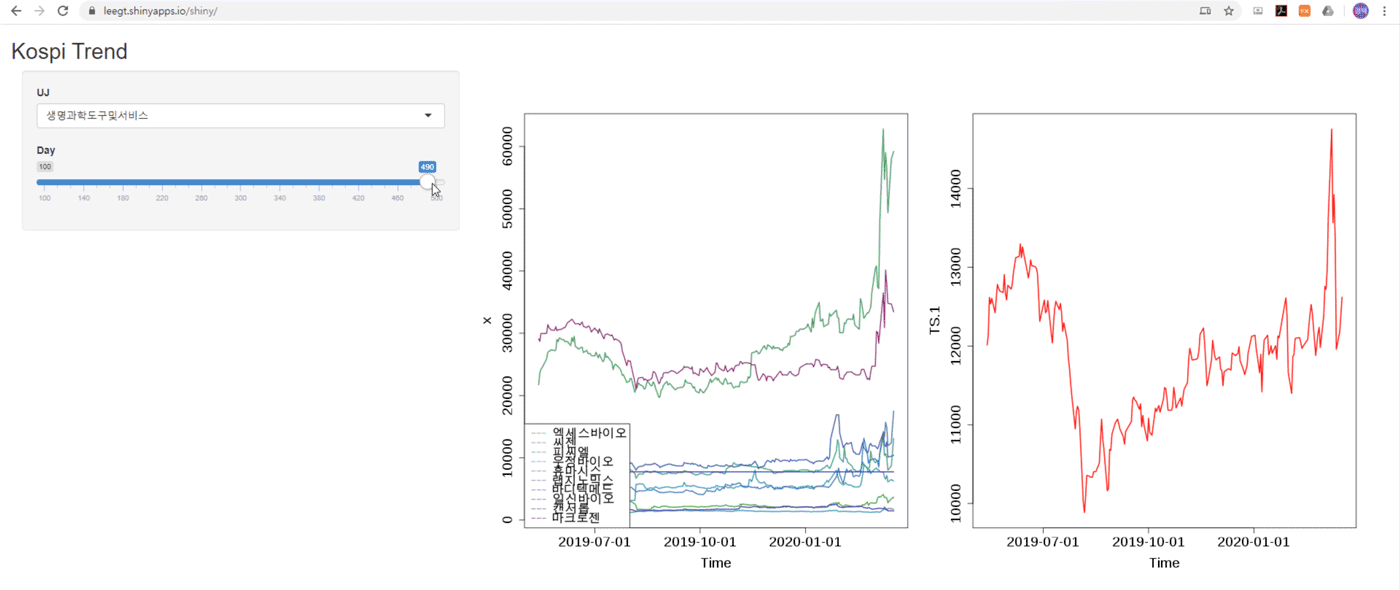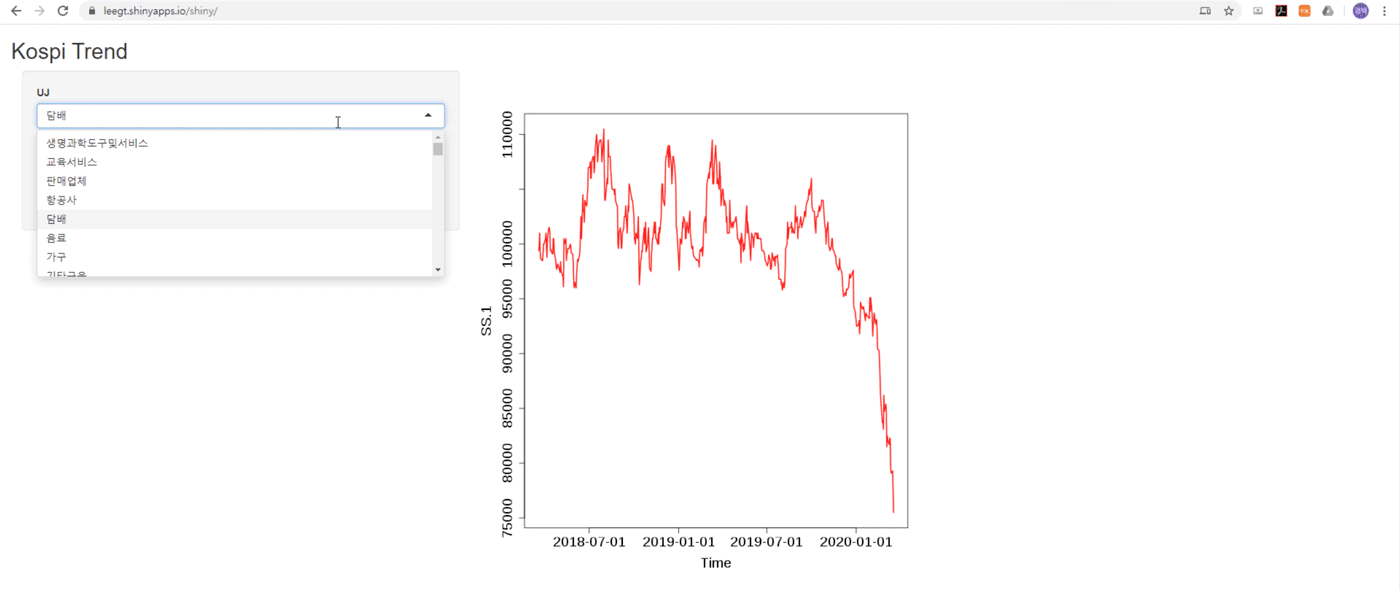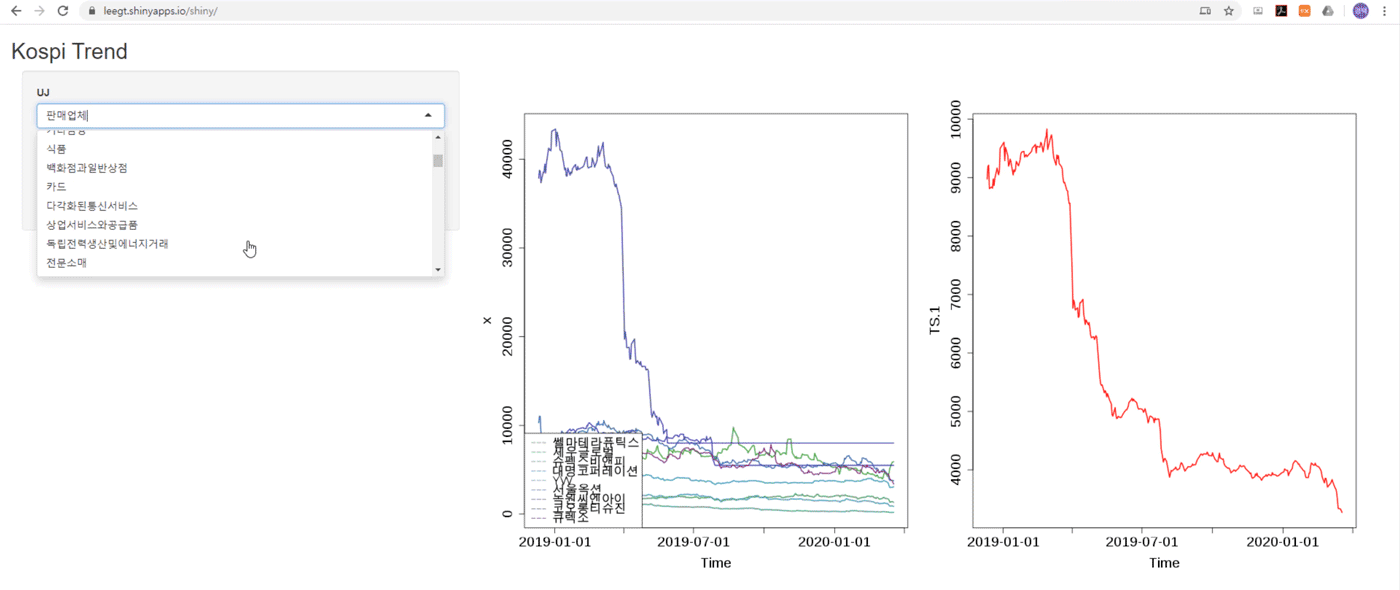
Every day after the stock market closes, the entire process—from collecting additional daily data to managing stocks by industry and visualizing them—is fully automated.
This course is a follow-up to <Web Crawling with R - Introductory Level>.
The course proceeds on the assumption that you have basic knowledge of the R language and crawling.
Who is this course right for?
Those who have basic proficiency in R
Those who need stock data
Those who want to build up foundational data for investing
8,543
Learners
528
Reviews
136
Answers
4.4
Rating
20
Courses
I am an unemployed scholar who majored in statistics as an undergraduate, earned a PhD in industrial engineering (artificial intelligence), and is still studying.
Awards ㆍ 6th Big Contest: Game User Churn Algorithm Development / NCSOFT Award (2018) ㆍ 5th Big Contest: Loan Delinquency Prediction Algorithm Development / Korea Association for ICT Promotion
Awards
ㆍ 6th Big Contest Game User Churn Prediction Algorithm Development / NCSOFT Award (2018)
ㆍ 5th Big Contest Loan Defaulter Prediction Algorithm Development / Korea Association for ICT Promotion (KAIT) Award (2017)
ㆍ 2016 Weather Big Data Contest / Korea Institute of Geoscience and Mineral Resources President's Award (2016)
ㆍ 4th Big Contest: Development of Insurance Fraud Prediction Algorithm / Finalist (2016)
ㆍ 3rd Big Contest Baseball Game Prediction Algorithm Development / Minister of Science, ICT and Future Planning Award (2015)
* blog : https://bluediary8.tistory.com
My primary research areas are data science, reinforcement learning, and deep learning.
I am currently doing crawling and text mining as a hobby :)
I developed an app called Marong that uses crawling to collect and display only popular community posts,
I also created a restaurant recommendation app by collecting lists of famous restaurants and blog posts from across the country :) (it failed miserably..)
I am currently a PhD student researching artificial intelligence.
I even developed a restaurant recommendation app by collecting blog posts and lists of top-rated restaurants across the country :) (though it failed miserably...) Now, I am a PhD student researching artificial intelligence.
I even developed a restaurant recommendation app by collecting lists of famous restaurants and blogs from all over the country :) (It failed miserably...) Now, I am a PhD student researching artificial intelligence.
All
23 lectures ∙ (3hr 55min)
Course Materials:
1. Orientation
01:47
All
8 reviews
4.9
8 reviews
Reviews 1
∙
Average Rating 5.0
Reviews 156
∙
Average Rating 5.0
Reviews 15
∙
Average Rating 5.0
Reviews 4
∙
Average Rating 5.0
Reviews 4
∙
Average Rating 5.0
Check out other courses by the instructor!
Explore other courses in the same field!