

Practical LLM Service Development for Spring Developers
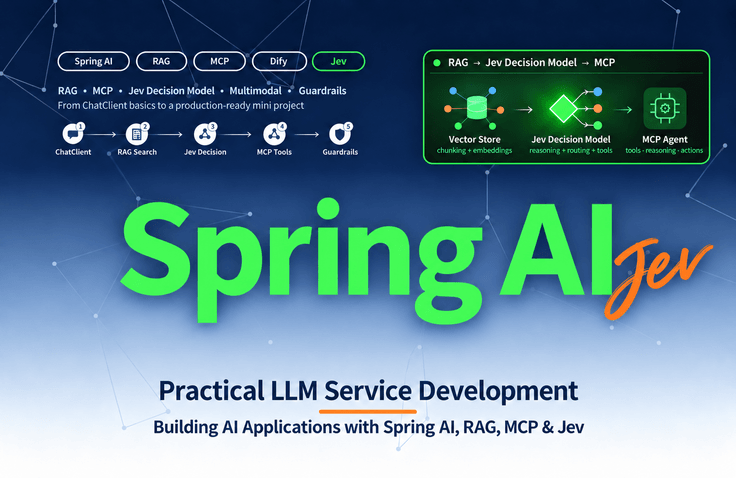
This is a practical course on building a RAG-based document search system using the OpenAI API and Spring AI in a Spring Boot environment. You will learn the entire process of developing an AI assistant step by step, from the concepts of Prompt Engineering, Vector Stores, and Embeddings to rapid prototyping with Dify, MCP tool integration, multimodality, and guardrails. You can learn practical application strategies by comparing direct implementation with the use of no-code tools. 🆕 [Update] Section 4 now includes a supplementary lecture (1 hour) on TypeSafe’s Jev decision-making model, covering how to design an agent’s decision-making logic in greater depth.
795 learners
Level Basic
Course period Unlimited

News
4 articles
Hello, I’m Lee Do-won (Kenneth).
I’ve opened the free course “Spring AI LLM Cost Monitoring — Build a Token Dashboard with One Line of Actuator”.
Why did I create this course?
The question I was asked most often while consulting on enterprise AI projects was this.
"We built a chatbot, but how much will this cost per month?"
LLM service costs vary with every request, responses can take several seconds, and the causes of failures lie outside our code. Yet many teams monitor them like ordinary web services and only discover the problem after receiving the bill.
Zero errors, Health UP, HTTP 200. An incident where input tokens increase several-fold while everything appears normal cannot be detected by conventional monitoring.
What this course does
With one line of Actuator, expose the token, latency, and error metrics that Spring AI is already recording.
With a single docker compose command, launch a Prometheus + Grafana token dashboard.
We find “occasionally slow requests” using p95 instead of the average.
With a single topK 4 → 20 setting, you will reproduce firsthand a “failure that looks normal” where input tokens increase approximately fourfold, and detect it on the dashboard.
No business code changes are needed. Just one dependency line and a few configuration lines.
Course Information
Duration: Approximately 1 hour (including hands-on practice)
Lab environment: JDK 21 or later, Docker Desktop, and an OpenAI API key or Ollama (free)
Provided materials: hands-on project, docker-compose, Grafana dashboard JSON, load scripts (bash · PowerShell), and step-by-step course materials
Metric names follow the Spring AI standard, so you can use the hands-on dashboard as-is in your project. Even without an API key, you can follow along all the way using Ollama.
Recommended for those who
Backend developers building a PoC or internal chatbot with Spring AI and preparing for launch
Actuator and Prometheus users who don't know what to monitor in LLM services
Team leads and architects who need to report the cost of adopting LLMs in numbers
If you want to go deeper
The custom metric that converts tokens into KRW costs, cost spike alerts, and distributed tracing (Jaeger) for viewing a single request step by step are covered in the 『Practical LLM Service Development for Spring Developers』 Section 16.
👉 Practical LLM Service Development for Spring Developers
If you get stuck while taking the course, please post your questions on the Q&A board. Questions like "I followed the steps, but the graph is empty" are welcome too.
The feedback you leave in your course review is a great help when creating the next course.
Thank you.
Best regards,
Dowon LeeHello. We’ve added a new supplemental lecture to the Practical LLM Service Development for Spring Developers (Part 1) course. In this approximately one-hour lecture, you’ll learn how to integrate TypeSafe AI’s recently released decision model, Jev, into a Spring Boot application.
Why was it added?
In Section 4, we covered how to useentity()to receive an LLM response as a Java object, as well as the practical pitfall of parsing breaking when the model wraps JSON in code fences. Whether you ask through a prompt or automate it withentity(), the limitation remains that you are ultimately "asking" the LLM to follow a particular format.
Jev takes a different approach. Instead of writing text, it chooses an answer from a predefined set of options and returns it along with its probability. In other words, the format is structurally guaranteed. Processing the same input in both ways makes it much clearer what to consider when designing "structured output." That is why we organized this content as an extension of Section 4.What will you learn?
The Concept of Jev and System One Models: What It Means to Return a “Typed Decision” Instead of Text
The difference between LLMs and Jev: descriptive answers vs. multiple-choice answers, and what each does well and poorly
Three question types (choice · score · noul) and the
/v1/systemonerequest structureCalling from Spring: Call the Jev API with
RestClientand use a Java enum to create choices and convert the response in a type-safe manner.Comparison demonstration: Analyze the same movie review using
entity()and Jev, then compare speed, format errors, confidence, and consistency.
Updated materials included
Section 4 Example Code (ch4): Two Review Analysis APIs (
/api/movies/review/llm,/api/movies/review/jev) and the Addition ofJevClientSupplementary lecture slides and course materials
Comparison test scripts:
review-compare.shfor macOS andreview-compare.ps1for Windows
Things to know in advance
Jev is not a feature of Spring AI, but rather a separate external service provided by TypeSafe AI. In the course, it is called directly using Spring AI's
RestClient, not itsChatClient.Jev is currently in the early access stage, so there may be a wait to obtain an API key. Jev is disabled by default in the example code (
jev.enabled=false), so you can proceed with the existing exercises as usual even without a key. If you don't have a key, watch the demonstration in the video and follow along with a focus on the concepts and code.As this service has just been launched, its pricing or API may change later. If any changes occur, we will notify you again through a new announcement.
📌 Go directly to the course: https://inf.run/VVpnV
If you have any questions while taking the newly added lessons or get stuck during the hands-on exercises, feel free to leave a comment. We’ll continue to regularly add content that you can use right away in your work.
Hello, I’m Lee Do-won.
"I’ve created Jenkins pipelines, but I’ve only heard of ArgoCD and GitOps as concepts."
"I’m at a loss as to how to design deployments for each dev, staging, and production environment."
For those facing these challenges, we have opened the “Practical GitOps CI/CD with Jenkins and ArgoCD” course on Inflearn.
Here’s what sets this course apart
• Beyond traditional Jenkins-based CI/CD, we also cover ArgoCD-based GitOps.
• We directly compare the Push (Jenkins) and Pull (ArgoCD) approaches on the same cluster. When someone makes a manual change with kubectl, you can see firsthand how one remains unchanged while the other automatically recovers, and experience the differences in how rollbacks and deployment histories are reviewed.
• Combine the two approaches to build a hybrid deployment pipeline from start to finish, with Jenkins Push for dev·staging and ArgoCD Pull (manual Sync approval) for production.
• You will practice essential deployment techniques needed for operations, including canary deployments, blue-green deployments, RBAC, approval procedures, incident response, and automatic rollbacks.
Practice Environment
We’ll proceed using just Docker Desktop. It works on both Windows and macOS, and you don’t need a cloud account such as AWS or any additional fees.
Recommended for
• Backend and infrastructure engineers who have used Jenkins but are new to ArgoCD/GitOps
• Those who want to move Kubernetes deployments from manual kubectl apply to automation
• DevOps and SRE professionals concerned with operational requirements such as deployment approvals, rollbacks, and audit trails
The total runtime is approximately 10–11 hours, and hands-on materials and a troubleshooting guide are also included.
👉 View the course: https://inf.run/dEjZE
If you have any questions, feel free to leave them in the comments or in the course Q&A!
We have newly launched the Practical LLM Service Development for Spring Developers (Part 1) course. Although it may feel a little overdue, this course covers what you need to learn to develop LLM applications using the Spring framework, which is familiar to Java developers. We hope you will take a great interest in it.
Why did I create this course?
These days, keywords like RAG, vector search, and AI agents can be found everywhere, but there aren’t many resources that address, at a practical level, “how to integrate them with a Spring Boot backend.”
This course incorporates into its curriculum the problems I encountered while debugging an actual RAG recommendation endpoint—including how chunking documents by token broke their semantic units and degraded search quality, and how I solved the problem by switching to paragraph-based chunking. Rather than simply showing you the correct code like a tutorial, we’ll follow along together to understand “why it doesn’t work → how to diagnose it → how to fix it.”
Recommended for the following people
Backend developers with Spring Boot experience who are new to developing LLM/AI services
Developers who want to apply RAG and vector search at the level of real-world projects, not just tutorials
Professionals who need to directly implement internal AI features (chatbots, document search, recommendations, etc.) using Spring.
Experience creating REST APIs with Spring Boot is all you need. No prior knowledge of AI/LLMs is required.
What will you learn?
1. Spring AI Core Fundamentals Basic usage of ChatClient, structured output, and streaming response implementation
2. Building a RAG Pipeline Vector store integration, comparison of document chunking strategies and hands-on troubleshooting, search quality improvement, and prompt design
3. Tool and Multimodal Expansion Integrating external tools using MCP (Model Context Protocol), processing multimodal inputs such as images, and integrating with Dify
4. Service Stabilization and Real-World Projects Applying guardrails, designing reliable services, and a mini project that integrates everything you have learned so far
The appendix also covers how to use AI coding tools and Ollama.
Series Guide
This release is Part 1 of the full series. Parts 2 and 3 will cover more advanced architectures and real-world cases, and once the entire series is released, we plan to offer a discount on the full package.
📌 Go to the course: https://inf.run/VVpnV
Feel free to leave any questions or inquiries about the curriculum in the comments. Through Part 1, I hope to take the first step with you toward integrating an LLM into your Spring service.
