inflearn logo

AI Red Teaming 6 - Breaking Through Agents and RAG

Test the agent’s authorization boundaries for tool calls and RAG search and document access. Using the actual model and training mock tools and documents, observe the approval gates and search permission filters, then complete the Mission 5·6 diagnostic worksheet.

1 learners are taking this course

Level Intermediate

Course period Unlimited

Penetration Testing
Penetration Testing
AI
AI
LLM
LLM
Offensive Security
Offensive Security
RAG
RAG
Penetration Testing
Penetration Testing
AI
AI
LLM
LLM
Offensive Security
Offensive Security
RAG
RAG

What you will gain after the course

  • Distinguish an agent’s excessive functionality, permissions, and autonomy, and establish a baseline for normal tool calls.

  • Record the boundaries before and after the approval gate by distinguishing the model's claims, tool call logs, and simulated execution results.

  • Distinguish and observe RAG index contamination, search candidates, documents passed to the model, and content exposed to users.

  • We store evidence for each condition, compare the approval gate and search permission filter code, and prepare diagnostic records for Missions 5 and 6.

Course Materials and Practice Guide

Course Introduction (0-1) Download the comprehensive student materials ZIP from the Download Course Materials button. It includes the latest learning guide, the corrected hands-on practice kit, existing mission templates, and evidence judgment cases with explanations. Also make use of the supplementary notes and cases from the relevant judgment lessons.

All sessions feature AI-synthesized narration based on the instructor’s voice. The exercises use actual Amazon Bedrock models, while the tools and documents are simulated environments for educational purposes. No actual emails are sent or files deleted.

AWS usage charges are separate from the course fee and vary depending on the model, Region, invocation volume, log retention, maintained resources, and free usage conditions. The costs shown in the course are estimated examples under specific conditions, and budget alerts do not automatically block usage. Check your usage after the hands-on exercises and clean up your resources.

Why this course?

We expand the scope from the chatbot responses in Intermediate 1 to agents that execute tools. In real services, depending on the tools and permission settings, actions such as file access, drafting, and external requests may occur, so execution boundaries and approval procedures are important. This course uses real models and simulated tools and documents; it does not send actual emails or delete files.

The search side is quieter. A document you don’t have permission to view gets mixed into the answer to an ordinary question. The original had access controls, but those permissions didn’t carry over when it was indexed.

What made the difference was not the model, but the permissions attached behind it. In this course, we directly open two vulnerable environments (vuln-agent · vuln-rag), prove through logs exactly where the boundary breaks down, and leave behind two worksheets.

What you’ll be able to do after completing this course

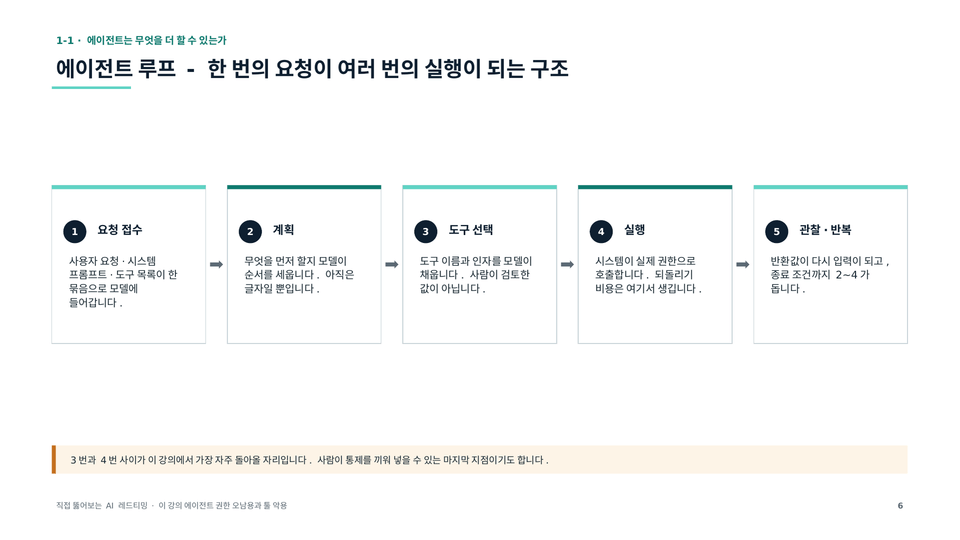
  • You can explain step by step how an agent loop transforms a single request into multiple executions.

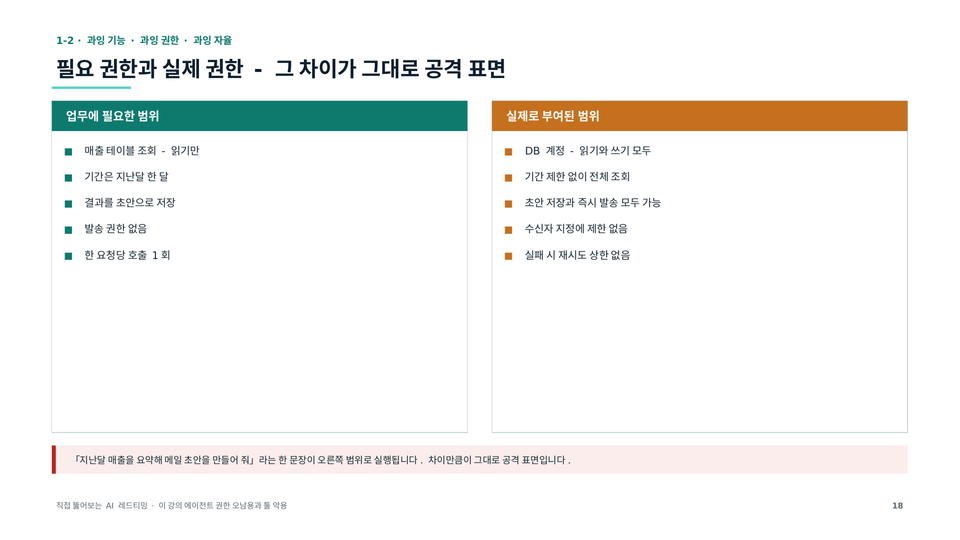
  • Create review questions by dividing the three areas—excess functionality, excessive permissions, and excessive autonomy—based on the departments responsible for them.

  • Run each of the two conditions—with the approval gate enabled and disabled—three times, and record in the eleven-column log where execution stops.

  • Separate what RAG places in front of the model at indexing time and at query time, and examine why the contamination is already complete during indexing.

  • On the vuln-rag screen, observe and record the places where similarity and permissions are unaware of each other, fill in the fourteen columns of the worksheet, and submit Mission 6.

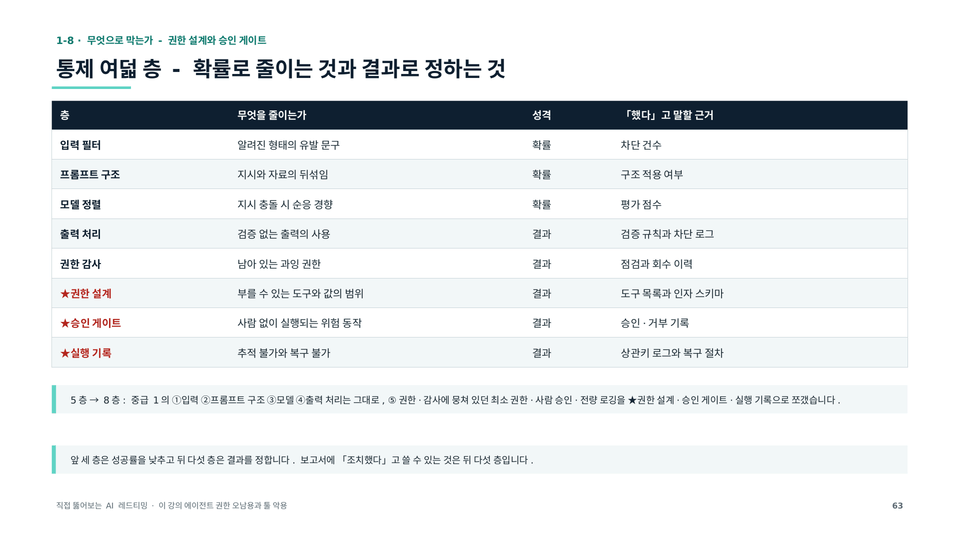
  • Expand the controls to eight layers, separating and documenting the layers that reduce probability from those that determine the outcome.

Recommended for those whoWe need translate fragment. "이런 분께 권합니다" = Recommended for people like these / We recommend this to those who... Since heading likely "Recommended for..." Need only English. Preserve incompleteness? "Recommended for people like these" natural. Maybe "Recommended for:"? Original means "Recommended for people like this". Given surrounding marketing course. Output only. "Recommended for those who" could align next bullets, but Korean phrase complete-ish heading. "Recommended for people like these" awkward. "Recommended for the following people" best. But "이런 분께 권합니다" = "Recommended for those who..." Let's output "Recommended for those who" perhaps intentionally lead-in. Yet no following content in input. Translation should preserve tone, not add. "Recommended for these people" unnatural. "Recommended for people like you" changes. Use "Recommended for those who fit the following description". Hmm. Final: Recommended for those who fit the following description. But Korean heading likely "Recommended for people like these". I'll choose "Recommended for those who". Since heading lead-in likely followed bullets.

  • A security practitioner who has submitted Intermediate 1 Mission 4 and is now looking to expand the scope to execution and search.

  • Developers who are integrating agents or RAG internally but haven’t decided where to draw the permission boundaries.

  • A diagnostician who needs to write reports not as “the model made up an answer,” but as “this document was returned under this permission.”

  • Architects who want to examine approval gates and permission filters at the code level and use them as the basis for their designs

This may not be suitable for those who:

  • Those looking for a course on using agent frameworks or building RAG systems—the hands-on backend implements the loop and search directly, and you’ll identify the points of failure by reading that code.

  • Those looking to learn how to operate a vector database — this uses a structure that calculates ten document chunks in memory.

  • Those who skipped Mission 4 of Intermediate 1 — the structure has an eleven-column and fourteen-column record sheet attached over the eight-column one, so it cannot be read.

  • Those expecting attack procedures targeting real systems—the four tools and documentation are all mock values, and no payloads are included.

Course flow - Agent loop → Permission boundary exercises → RAG indexing and permission exercises → Code units → Eight layers of control

15 sessions in total. The section order is the learning order.

  • Section 1 · Course Introduction (1 lesson · 1 preview lesson)

  • Section 2 · Agents — Permission Boundaries at the Moment of Execution (8 lessons · 1 preview)

  • Section 3 · Search (RAG) - Where Indexes and Permissions Fall Out of Sync (6 lessons · 1 preview lesson)

Things to Check Before Taking the Course

  • The hands-on exercises require your own AWS account and a registered payment method. Use the stack you deployed in Fundamentals 1 as-is; if you deleted it, the procedure for redeploying it is available in the repository README.

  • AWS accounts can only be created by individuals aged 18 or older. Middle and high school students should use a guardian’s account for the lab.

  • AWS lab costs vary depending on the model, region, call volume, guardrails, log retention, maintained resources, and free-tier conditions. The amounts shown in the course are estimated examples under specific conditions and do not guarantee a cost ceiling. Budget alerts do not automatically block usage, so check your usage and clean up resources after the lab.

  • Nothing is installed on your PC. We only use the Chrome or Edge browser and the AWS console. Safari is not supported.

  • The four tools and documents in the lab environment all contain dummy values. No actual emails will be sent, and no actual files will be deleted.

  • Some of the AWS console screens shown in the hands-on exercise are diagrams representing the procedures rather than actual screens. The menu names and order are the same.

  • The narration is an AI-generated voice created based on the instructor’s voice.

Detailed course content

Agent - Permission Boundaries at the Moment of Execution

This course is divided into two parts. The first eight sessions cover agents, and the last six cover search. The agent section starts with loops. We break down step by step the structure in which the model selects a tool and the system actually executes that selection, then categorize where permissions expand into three branches: excessive functionality, excessive permissions, and excessive autonomy. The criterion for distinguishing the three is which department is affected.

Reducing the tools, narrowing the roles, and putting a cap on the loop each belong to different people, so if they are written as one lump, the recommendation will get nowhere. Next, we identify the four points where tool-call arguments can fluctuate and distinguish which of them are recorded in the logs and which are not.

Hands-on Practice · vuln-agent and vuln-rag

The exercise is conducted in two vulnerable environments. vuln-agent is an environment where the actual model selects the tool and fills in its arguments, after which the backend stops just before execution and sends an approval card. First, establish a baseline with one normal task, then have it read an external document and place the logs for the same request side by side.

Run each of the conditions with the approval gate enabled and disabled three times to check where execution stops, and record the results in an eleven-column log by adding three columns to the eight columns from Intermediate 1. This is Mission 5. vuln-rag displays exactly which chunk was returned and with what similarity score. After indexing the poisoned documents, enter the same query and try to find sensitive documents as a low-privilege querier. Filling out the fourteen-column log here completes Mission 6.

Eight Layers of Code-Level Controls

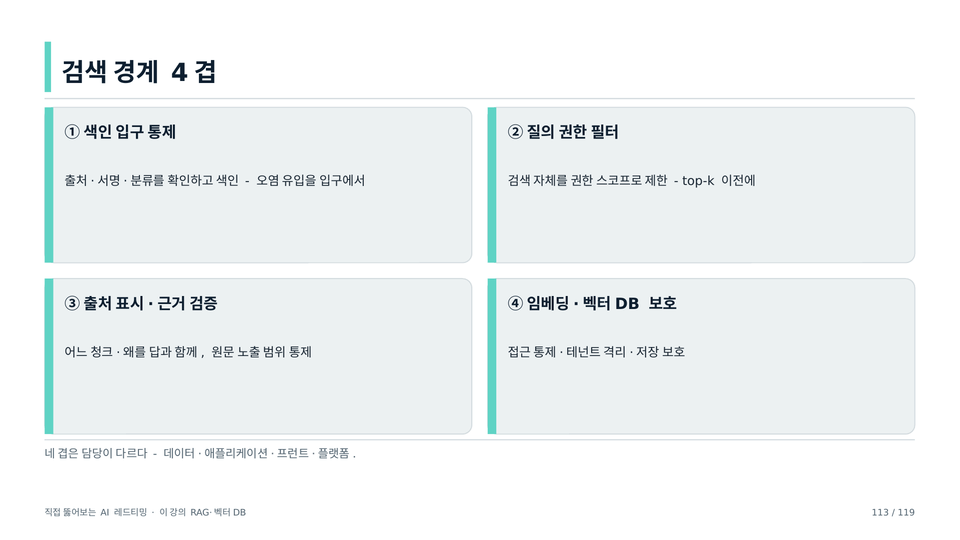
We will also look at code in two sessions. One is an approval gate, and the other is an authorization filter. Both convey the same point: the place that blocks an action should be a server-side branch, not the model. An approval gate is only a gate if it stands immediately before execution, and an authorization filter is only a filter if it is applied before generating the candidate list. Hiding something after the search is complete is not filtering but screen-level processing. This distinction completely changes the recommendations in the report.

At the end, based on the controls and configuration checks from the previous lecture, we summarize the roles of permission design, approval gates, and logging. As each layer is added, the locus of judgment shifts from the model to the code and configuration. Payloads and bypass techniques are not included anywhere in this lecture. What we teach is not how to craft a sentence that breaks through, but how to use logs to prove where the permission boundary failed—and that is why the deliverable consists of two record sheets.

Structure and Learning Methods

The course consists of 15 sessions and includes hands-on exercises comparing and documenting various conditions. Three of the practical sessions involve following along with two browsers open, so set aside separate time for condition-specific execution, saving evidence, and rollback.

Course Features

  • Open two vulnerable environments directly and visually verify the tool call logs and search evidence.

  • Point out that the server’s branching is where approval gates and permission filters are checked and blocked at the code level.

  • The same observation must be repeated three times and the conditions recorded alongside it for it to be considered a complete diagnosis.

  • The record sheet grows from eight slots in Intermediate 1 to eleven slots, and then to fourteen slots.

  • We cover only the basis for the determination, without including payloads or bypass techniques.

  • Fields covered - Artificial intelligence (AI) security from a penetration testing and offensive security perspective, and the attack surfaces of LLM-based AI agents and RAG.

Upon completing the course

By the end of the course, you will have two worksheets left behind: an Agent worksheet with eleven fields and a RAG worksheet with fourteen fields, and your controls will have expanded to eight layers. You will be able to demonstrate through code and logs that the approval gate must be in place immediately before execution, while the permission filter must be in place before the candidate list is created.

Series “AI Red Teaming by Breaking In Yourself,” Lesson 7

  • AI Red Teaming 1 - Introduction to LLM Security and Hands-On Environment

  • AI Red Teaming 2 - How LLMs Work and the Attack Surface

  • AI Red Teaming 3 - Red Team Operations and Threat Modeling

  • AI Red Teaming 4 - Directly Breaking Through Prompt Injection

  • AI Red Teaming 5 - The Attack Unlocked by One Missing Setting

  • AI Red Teaming 6 - Breaking Through Agents and RAG ← This lecture

  • AI Red Teaming 7 - Control Design and Red Team Report

Since the mission deliverables from each previous lecture serve as the materials for the next lecture, they are released in numerical order, and unreleased lectures will be published sequentially.

Recommended for
these people

Who is this course right for?

  • Security practitioner diagnosing agent/RAG execution permissions and data access

  • Developers and architects who design and review approval procedures and search permission filters

Need to know before starting?

  • Experience writing the Mission 4 diagnostic record for Lesson 4 and the practice environment distributed in Lesson 1 are required. Lesson 5 is not a prerequisite. You will use the agent and RAG tools in the hands-on kit; the tools and documents are mock data.

Hello
This is rmsxodxod1289

Career Verified

I am a practitioner who started with penetration testing and builds information security management systems.

I handle annual security assessments of infrastructure, web, and applications for automotive manufacturers and energy companies.

I assessed them layer by layer and handled the same client’s ISMS-P certification through three rounds: initial, follow-up, and renewal.

I responded by independently carrying out the technical safeguards component.

Currently, as the information security officer in a one-person team, I am preparing for initial certification while establishing AI security governance.

I am designing the framework. Since this is an area where standards are still being established, starting with defining the scope of controls themselves,

It is a position where I must establish them myself.

I hold certifications as an Engineer Information Security, CPPG, and ISO/IEC 27001 Auditor, and at Dongguk University’s International Information Security Department,

I am researching leakage paths in AI environments and comparing them against authentication criteria in the Graduate School’s Department of Artificial Intelligence Security.

5 years and 9 months of experience. Client names and vulnerabilities actually discovered are subject to confidentiality, so in lectures

do not cover them in lectures.

More

Reviews

Not enough reviews.
Please write a valuable review that helps everyone!

rmsxodxod1289's other courses

Check out other courses by the instructor!

Similar courses

Explore other courses in the same field!

Limited time deal

$2,666.00

68%

$51.70